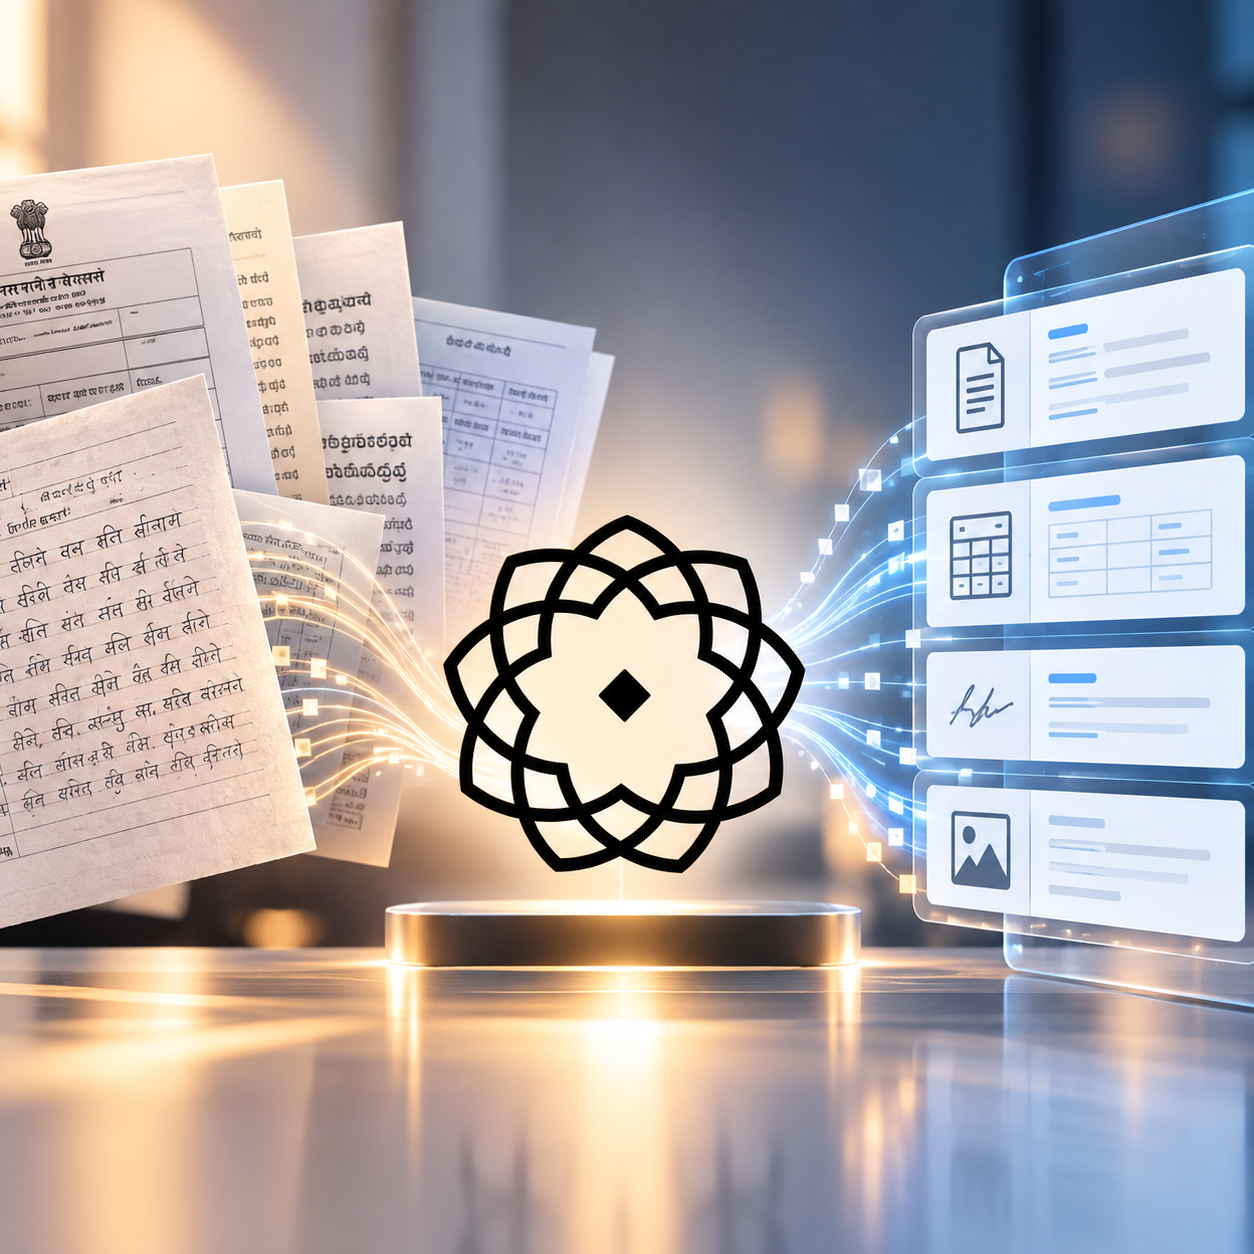
Indian artificial intelligence startup Sarvam AI has launched Sarvam Vision 2.1, an upgraded version of its document intelligence model, adding capabilities for Indic handwriting recognition, complex table parsing and structured data extraction.
The model is designed to process documents across English and 22 Indian languages, with a focus on converting scanned documents, forms, tables and handwritten material into structured digital information. The update builds on Sarvam Vision, which was introduced in February 2026 as part of the company's sovereign AI model portfolio.
Sarvam said the latest version addresses feedback received following the earlier model's rollout, particularly around usability, hallucinations and inconsistencies. The company has also optimised its inference stack to support production workloads at a lower price point than initially announced.
Among the additions is key-value extraction from tables and forms. This allows the model to identify specific information from complex documents, including multi-page tables and forms containing multiple fields. It can also recognise handwritten content in Indian languages and extract structured information from handwritten forms.
The company said it trained these capabilities using a combination of synthetic and real-world datasets, including handwritten and printed forms across different languages. The model underwent supervised fine-tuning followed by reinforcement learning with verifiable rewards.
Alongside Vision 2.1, Sarvam has released its Indic OCR Bench, a benchmark designed to evaluate optical character recognition accuracy across India's 22 official languages. The dataset contains 6,909 samples, including 6,609 across Indian languages and 300 in English, sourced from material such as newspapers, textbooks, brochures and historical writings dating from 1800 to the present.
According to Sarvam's own evaluations, Vision 2.1 recorded an overall accuracy of 87.39 on the Indic OCR benchmark. It also scored 87.3 on olmOCR-Bench, which evaluates document processing across areas including tables, multi-column pages, mathematical content, old scans and dense text. These performance figures are company-reported benchmark results.
The model is being made available through Sarvam's document AI tools. Its Digitize API can convert documents, tables and handwritten material into structured text, while the Extract API is designed to retrieve key-value pairs, tables and form fields. Sarvam's documentation lists document intelligence, text extraction, table conversion and structure preservation from PDFs and scans among the model's primary applications.
Disclaimer: This article may include information derived from interviews, press releases, public statements, research, company communications and other publicly available or third-party sources. Such material may be summarised, paraphrased or contextualised for journalistic and editorial purposes. All rights in third-party content remain with their respective owners.